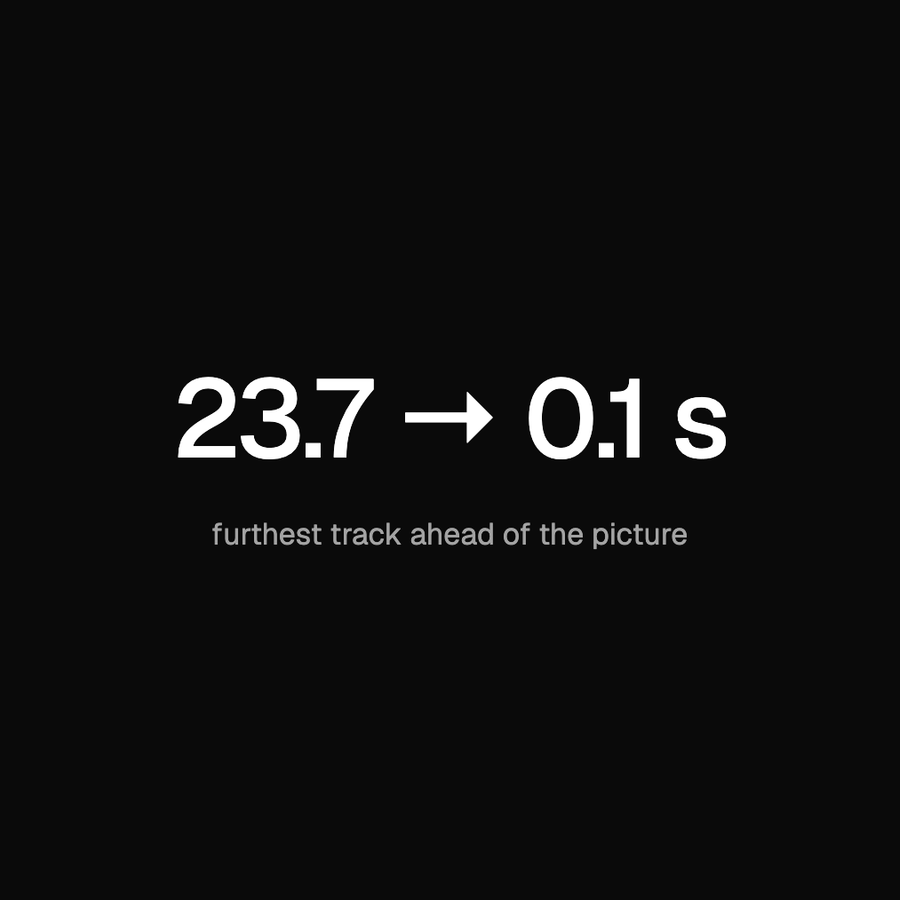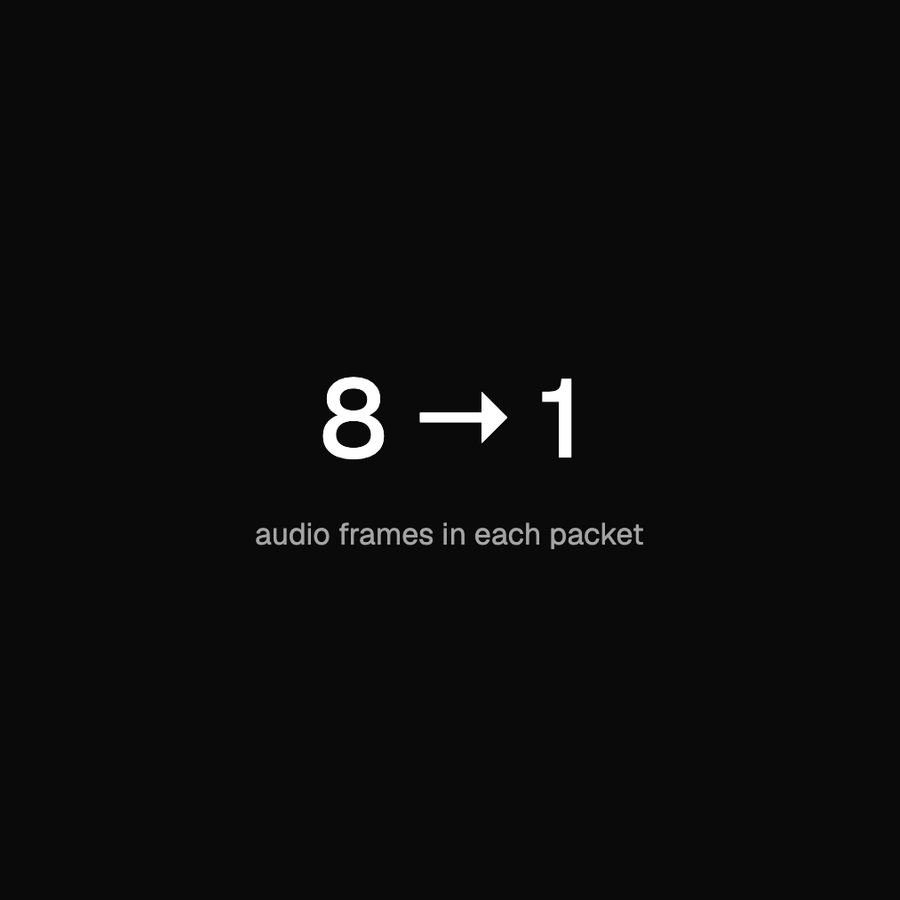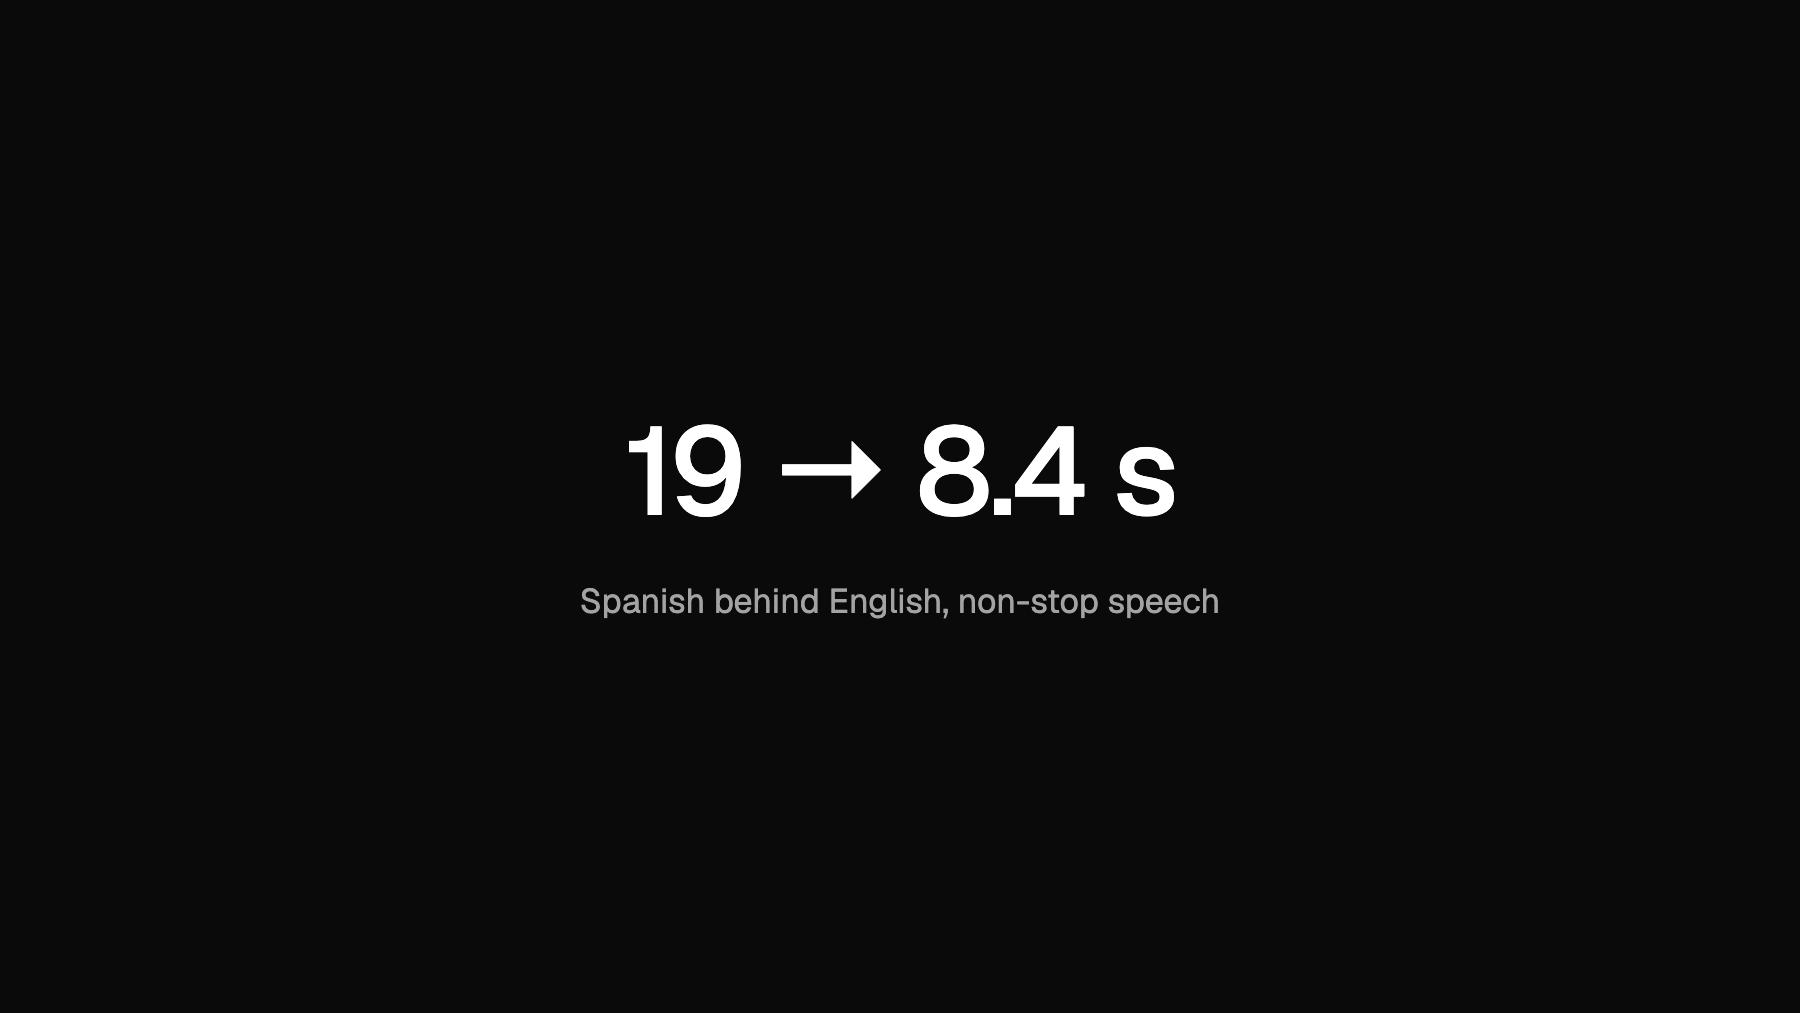
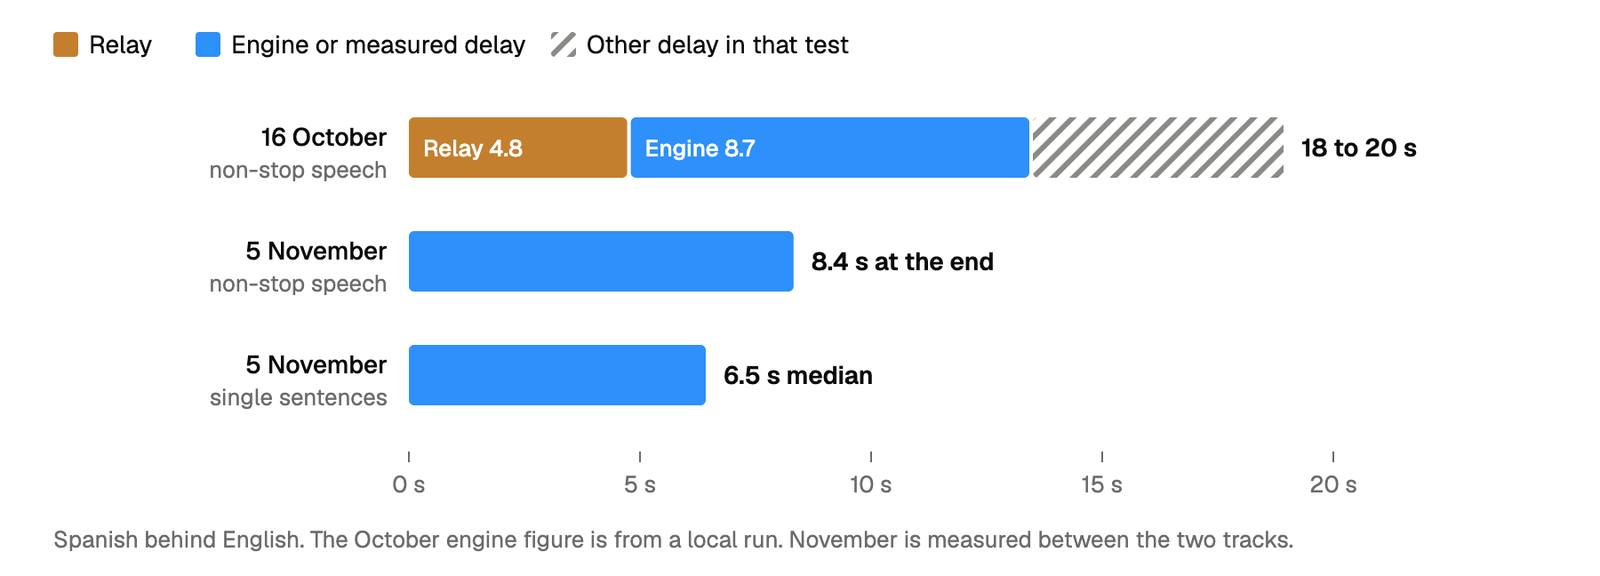
On 16 October we ran an English to Spanish test of AI live interpretation in production. After about 8 seconds on the first sentence, Spanish settled at 18 to 20 seconds behind the English track and stayed there. We shipped two changes on 17 October. A test on 5 November, on the same kind of non-stop speech, had Spanish finishing 8.4 seconds after the English, and about 6.5 seconds behind on single sentences with pauses around them. The largest parts we traced were 4.8 seconds in a relay that sat between the interpreter and the viewers, and about 2 seconds in how the engine cut speech into pieces. This post sets out what we measured and what we changed.
Context
The interpreter is a service that listens to the audio of a broadcast, recognises the speech, translates it, synthesises a voice in the target language and publishes the result as another audio track of the same broadcast. Speech recognition, translation and voice synthesis are done by outside AI services. Our engine cuts the incoming audio into pieces, sends each piece through those three steps, and plays the results back out in order.
The measurement in this post compares the interpreted track with the original track as a viewer's player has them. It is not a measurement against a person standing in a room. Both tracks go through the same player and the same delivery delay, so the delay common to both cancels. We come back to this at the end.
What we saw
The test used an unlisted broadcast from our own test account, in production, English to Spanish, for about three minutes. The source was a 33-second recording of continuous English, looped. That is deliberately hard: there are no natural pauses in it, and a real sermon has more. We fetched the broadcast's HLS renditions afterwards and transcribed both audio tracks with an open-source speech model run on our own machine, using its timed output. The two renditions start at the same presentation timestamp (0.000 s and -0.021 s), so times in the two transcripts can be compared directly.
Spanish was 8 seconds behind on the first sentence and then settled at 18 to 20 seconds. Two observations from the first look.
Spanish takes longer to say. The same passage took 12.2 seconds in English and 18.4 in Spanish, about 1.5 times as long. An interpreter that says every sentence at its natural pace cannot keep up with continuous speech. It has to speed up or fall behind. The engine speeds the voice up when audio is waiting, to a maximum of 1.4 times. In steady state that was enough to stop the delay growing: 31.9 seconds of Spanish came out for every 33.1 seconds of the English loop. It was not enough to bring the delay down, because there is no pause in continuous speech for the backlog to drain.
Our own number was wrong. The engine logged target es-ES is 6.9s behind, skipping a 3.3s sentence. Viewers were hearing 18 to 20 seconds. The engine's figure left out the time spent waiting for a sentence to finish, so it read far lower than what a listener experiences. We had been watching a metric that understated the problem by about 11 seconds.
What we ruled out
- The viewer's playback delay. The interpreter does not read the broadcast from the player's side. It reads its input over RTMP straight from the ingest server, so HLS delivery is not part of this path.
- CPU. The interpreter task had 2 vCPUs and used about 2 percent.
- A start-up burst. The first five seconds of input arrive faster than real time. The pacing absorbs this.
- Alignment between tracks in our muxer. It contributes at most 1.6 seconds, which we describe in a separate post.
What we changed
1. The relay: 4.8 seconds. Each interpreted language went out over SRT to a relay in front of the ingest server. SRT negotiates latency by taking the larger of the two sides' settings. The interpreter asked for 1 second. The relay's listener asks for 4, because it exists to receive from venues with poor uplinks, so 4 won. The relay then probes each stream for 2 seconds before passing it on. We measured the total by sending music through unchanged on the same test broadcast and cross-correlating the original and Spanish tracks (correlation 1.00): the route added 4.8 seconds. The two settings give 4 and 2 seconds. They do not add to 4.8, and we did not break the figure down further.
The engine now publishes each language directly to the ingest server over RTMP, the address the relay itself publishes to. The old route is still there behind a setting, in case we need it.
// outputURL is where the engine publishes a language. Straight to ingest's
// RTMP server by default: over SRT, ingest's receive buffer (sized for venue
// uplinks) and the relay behind it put every sentence about 5 s later.
func (j *job) outputURL(t Target) string {
	if j.m.cfg.Output == "srt" {
		return fmt.Sprintf("srt://%s:%s?streamid=%s,key=%s&latency=%s", /* ... */)
	}
	return fmt.Sprintf("rtmp://%s:%s/%s/%s?key=%s", /* ... */)
}
2. Cutting speech where the speaker pauses. The engine used to cut a piece at 3.5 seconds wherever it was. On the test speech that forced a cut in 48 of 54 pieces, 89 percent, often mid-word. A word split in two is recognised as two other words, and a sentence cut in the wrong place is translated as two sentences that mean something else. Two examples from the test: "welcome anyone who is new" came out as "¿Quién es nuevo?", and "we will read together" as "Leímos".
Now, once a piece has run 3 seconds it ends at the first pause of 140 milliseconds. At 4.5 seconds it is cut at the quietest 60 milliseconds of its last second, and the remainder carries into the next piece.
3. Pieces voiced in the order spoken. Two recognisers run at once, so a short piece after a long one finished first and was translated and voiced ahead of it. "Come near." came out before the sentence it ends. A small ordering stage now holds finished pieces until the earlier ones are done.
4. Pacing starts sooner. The voice reaches its full 1.4 times speed when 2.5 seconds of audio are waiting, where it used to need 5. In the code's comment, this kept Spanish about a second closer to the speaker on non-stop speech.
5. A real figure in the logs. Each language now logs once a minute how far behind the speaker its sentences went out, as a median with the longest and the count of skipped sentences.
What we tried and why it lost
Keeping the short fixed cut. The 3.5-second cut was the shortest piece we used, and it was what damaged meaning in the test. We kept sentence-level translation and moved the cuts to where people pause.
Lowering the relay's latency for everyone. The 4-second setting is there for venue uplinks, and other publishers use that relay. We routed the interpreter around it instead.
The numbers
| What | Before | After | How measured |
|---|---|---|---|
| Spanish behind English, as a viewer's player has them, non-stop speech | 18 to 20 s (first sentence 8 s) | 7.0 s at the start, 8.4 s at the end | Production tests on 16 October and 5 November, one language pair. Different test speech and method, see below |
| Spanish behind English, single sentences with long pauses | Not part of that test | 5.7 to 6.7 s at the start of each sentence (median 6.5) | Production test, 5 November, six sentences |
| Relay route, original vs Spanish track | 4.8 s | Route removed | Music passthrough, cross-correlation 1.00, before only |
| Engine alone, dense speech: median / p90 / max | 8.7 / 10.2 / 11.3 s | 6.6 / 7.6 / 7.8 s | Local run, 198 s of non-stop speech, same machine |
| Engine alone, 3-minute sermon with natural pauses, median | 6.1 s | 6.4 s | Local run |
| Forced mid-speech cuts, sermon | 24 | 2 | Local run |
| Engine's own report in production | 6.9 s behind, skipping a 3.3 s sentence (old-style figure, which left out the sentence wait) | Single sentences: 5.2, 5.5, 5.8 s medians. Non-stop speech: 9.9, 8.1, 8.5 s medians, longest 10.4 s, nothing skipped | Production logs, 16 October and 5 November |
Later logs. The new per-minute report ran in production from 17 October through 1 November. Across 71 one-minute reports, almost all from internal tests, the median of the Spanish minute-medians was 7.2 seconds (31 minutes) and French 6.5 seconds (24 minutes). Chinese, Japanese, Italian and German had four reports each, between 4.7 and 5.8 seconds. Of 464 Spanish sentences, 6 were skipped, which is 1.3 percent. These are the engine's own figures, not the viewers'.
Measuring it again
We re-ran the test on 5 November on an unlisted broadcast, started the way a creator starts one, by streaming from software with interpretation already on. The source was synthesised English: six single sentences with about 18 seconds of silence after each, then about two and a half minutes of non-stop speech. We recorded both audio tracks from the same HLS stream a viewer gets, and timed when sound starts and stops in each. No transcription was involved, so nothing depends on matching words across languages.
| Part of the test | Spanish starts behind | Spanish ends behind |
|---|---|---|
| Six single sentences | 5.7, 5.9, 6.6, 6.7, 6.6, 6.3 s | 5.8, 6.4, 7.3, 8.2, 7.4, 7.3 s |
| About 150 s of non-stop speech | 7.0 s | 8.4 s |
Nothing was skipped. The sound of a track only tells us when speech starts and stops, so for the middle of the non-stop passage we rely on the engine's own report of 8.1 to 9.9 seconds.
The engine's own report now matches what reaches viewers. On single sentences the engine says 5.2 to 5.8 seconds and the tracks say 5.7 to 6.7. On non-stop speech the engine says 8.1 to 9.9 and the tracks end at 8.4. That matters as much as the speed-up: the number we watch in production is now one we can trust.
The two tests used different speech and a different way of comparing the tracks, so treat the improvement as about 10 seconds rather than an exact figure.
What this costs us
Voices speak up to 1.4 times faster when audio is waiting. A sentence that would leave a language more than 10 seconds behind is skipped whole. In a 3-minute production test in October that was one sentence, 6.1 seconds long, skipped at 4.2 seconds behind. The direct RTMP route runs over TCP, without SRT's loss recovery, so it stays inside our own network. On a talk that already has natural pauses, such as the sermon sample, the engine-side median did not improve: 6.1 seconds before and 6.4 after.
What we are working on now
Non-stop speech is the hardest case for interpretation, because a sentence has to finish before it can be translated. Bringing it closer to the single-sentence figure is what we are working on now.
What we got wrong
We trusted an internal "behind" figure that left out a stage. The first thing we should have done on seeing a lag was compare two tracks of a real broadcast in a player, as we did here.
How we measured, and what we left out
Viewer-side delay, November: record each audio rendition from the live HLS stream with timestamps kept, check both start at the same time (they were 0.02 seconds apart, which we corrected), and time when sound starts and stops in 50 millisecond windows. October: transcribe both tracks with an open-source speech model run locally and compare sentence times. Engine-side: the engine's per-minute production report, and local runs of the same engine on recorded speech, with the same machine for before and after. Spanish is the language we measured at the viewer end; the other languages are engine-side figures. These figures compare the two tracks in one player, so they do not include the delivery delay every viewer has on every track. We have left out stream names, keys, internal addresses, account details, and the broadcasts we tested on. The test broadcasts and their files were deleted after each test.